GLM-5.3 (max) vs Claude Opus 5.5 (max)
Results updated 3 November 2026 · Both in Claude Code · How we benchmark
Verdict


Not comparable yet: Claude Opus 5.5 (max) is not yet ranked.
- Cost per task
- $0.48 vs $0.83
- Time per task
- 4.3 min vs 4.5 min (estimated)
- Tokens per attempt
- 489k vs 530k
- Image input
- No vs Yes
GLM-5.3 (max), Claude Code scores higher on Earth-Bench V2; Claude Opus 5.5 (max), Claude Code scores higher on GeoBenchX and GS-QA2. GLM-5.3 (max), Claude Code is cheaper and faster: $0.48 against $0.83 per task, and 4.3 min against 4.5 min.
Not yet ranked. Claude Opus 5.5 (max), Claude Code. Not in the Agent Index, cost and time charts until it has a score on every index evaluation. Results so far are in the side-by-side table.
Where they differ most
By kind of work, share of tasks passed, 0 to 100 · Higher is better
| Kind of work | GLM-5.3 (max) | Claude Opus 5.5 (max) |
|---|---|---|
| Recognising infeasible requests | 58 | 79 |
| Climate and time series | 76 | 60 |
| GIS analysis | 81 | 93 |
| Spatial statistics | 38 | 50 |
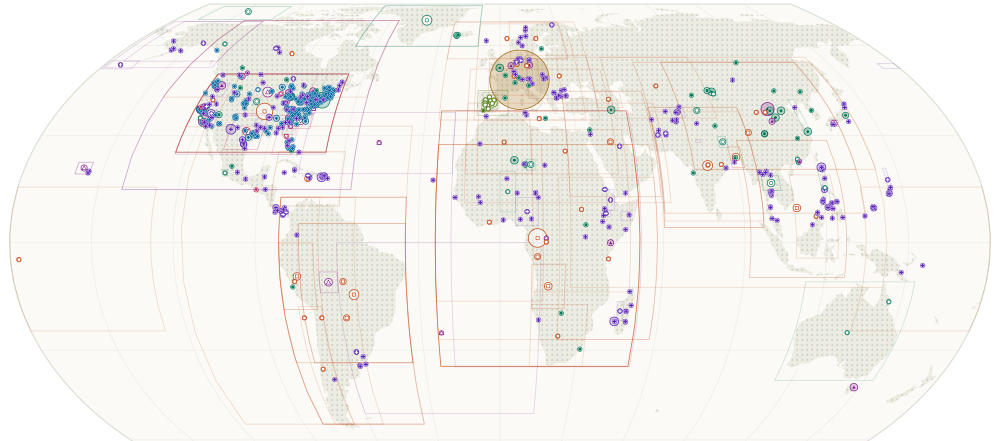 Where the tasks are set: each kind of work links to its tasks and scores
Charts for each: GLM-5.3 (max), Claude Code · Claude Opus 5.5 (max), Claude Code.
Side by side
| Metric | GLM-5.3 (max), Claude Code | Claude Opus 5.5 (max), Claude Code |
|---|---|---|
| Geospatial Agent Index: Text only | 73 | 79 |
| Geospatial Agent Index: Text + vision | No image input | No data |
| Earth-Bench V2 score | 74 | 71 |
| GeoBenchX score | 65 | 74 |
| GS-QA2 score | 81 | 92 |
| Vision agents score | No image input | 98 |
| GeoAgentBench score (Guided workflows; not in the Agent Index) | 98 | 100 |
| GeoAnalystBench score (Guided workflows; not in the Agent Index) | 95 | 100 |
| OGD4All score (standalone; in no index) | 96 | 95 |
| GeoNatureAgent score (standalone; in no index) | 100 | 100 |
| MultiGlobeQA score (standalone; in no index) | 74 | 76 |
| GeoAgentEval score (standalone; in no index) | 88 | 100 |
| Remote sensing and raster analysis score | 80 | 88 |
| GIS analysis score | 81 | 93 |
| Climate and time series score | 76 | 60 |
| Spatial statistics score | 38 | 50 |
| Making maps score | 75 | 77 |
| Recognising infeasible requests score | 58 | 79 |
| Cost per task | $0.48 | $0.83 |
| Time per task (at 100 output tokens/s) | 4.3 min | 4.5 min (estimated) |
| Tokens per attempt | 489k | 530k |
| Turns per attempt | 13.4 | 12.0 |
| Input price per 1M tokens | $1.40 | $4.00 |
| Output price per 1M tokens | $4.40 | $20.00 |
| Context window | 1,048,576 | 1,000,000 |
| Image input | No | Yes |
| Developer | Z.ai | Anthropic |
Frequently asked questions
Which scores higher on the Geospatial Agent Index, GLM-5.3 (max), Claude Code or Claude Opus 5.5 (max), Claude Code?
Not comparable yet: Claude Opus 5.5 (max), Claude Code is not yet ranked.
Which is cheaper per task, GLM-5.3 (max), Claude Code or Claude Opus 5.5 (max), Claude Code?
GLM-5.3 (max), Claude Code, $0.48 to $0.83.
Which writes fewer output tokens per task, GLM-5.3 (max), Claude Code or Claude Opus 5.5 (max), Claude Code?
GLM-5.3 (max), Claude Code, 15k to 23k.
Which has the larger context window, GLM-5.3 (max), Claude Code or Claude Opus 5.5 (max), Claude Code?
GLM-5.3 (max), Claude Code, 1,048,576 tokens to 1,000,000 tokens.