Qwen 3.8 27B (Reasoning) vs Claude Opus 5.5 (xhigh)
Results updated 25 October 2026 · In Qwen Code and Claude Code, so part of any gap can come from the harness · How we benchmark
Verdict


Claude Opus 5.5 (xhigh) clearly beats Qwen 3.8 27B (Reasoning) by 16 points, and is faster; Qwen 3.8 27B (Reasoning) is cheaper.
- Cost per task
- $0.22 vs $0.25
- Time per task
- 4.7 min (estimated) vs 1.4 min
- Tokens per attempt
- 840k vs 174k
- Image input
- Yes vs Yes
Claude Opus 5.5 (xhigh), Claude Code scores higher than Qwen 3.8 27B (Reasoning), Qwen Code on all 3 evaluations scored for both. Qwen 3.8 27B (Reasoning), Qwen Code is cheaper ($0.22 against $0.25 per task), but Claude Opus 5.5 (xhigh), Claude Code is faster (1.4 min against 4.7 min).
Where they differ most
By kind of work, share of tasks passed, 0 to 100 · Higher is better
| Kind of work | Qwen 3.8 27B (Reasoning) | Claude Opus 5.5 (xhigh) |
|---|---|---|
| Making maps | 65 | 88 |
| Recognising infeasible requests | 62 | 82 |
| GIS analysis | 75 | 94 |
| Remote sensing and raster analysis | 77 | 89 |
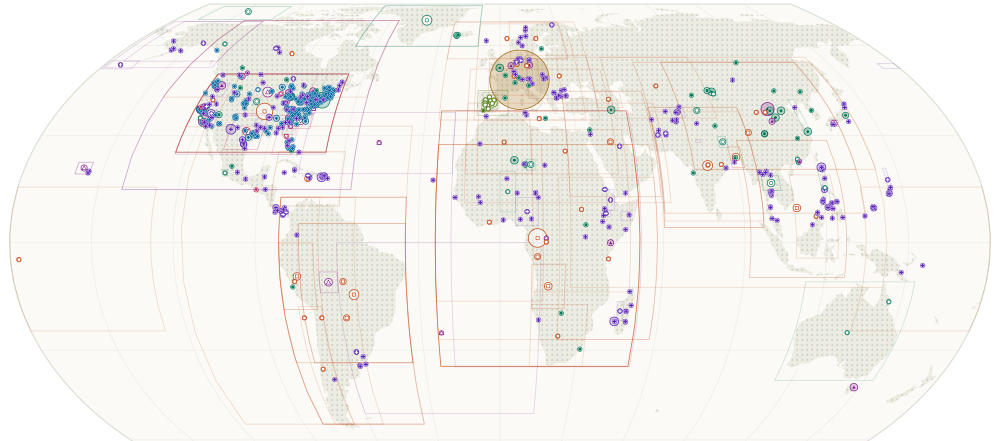 Where the tasks are set: each kind of work links to its tasks and scores
Charts for each: Qwen 3.8 27B (Reasoning), Qwen Code · Claude Opus 5.5 (xhigh), Claude Code.
Side by side
| Metric | Qwen 3.8 27B (Reasoning), Qwen Code | Claude Opus 5.5 (xhigh), Claude Code |
|---|---|---|
| Geospatial Agent Index: Text only | 69 | 85 |
| Geospatial Agent Index: Text + vision | No data | 88 |
| Earth-Bench V2 score | 69 | 77 |
| GeoBenchX score | 63 | 83 |
| GS-QA2 score | 75 | 94 |
| Vision agents score | No data | 97 |
| GeoAgentBench score (Guided workflows; not in the Agent Index) | 94 | 98 |
| GeoAnalystBench score (Guided workflows; not in the Agent Index) | 79 | 100 |
| OGD4All score (standalone; in no index) | 97 | 96 |
| GeoNatureAgent score (standalone; in no index) | 100 | 100 |
| MultiGlobeQA score (standalone; in no index) | 74 | 79 |
| GeoAgentEval score (standalone; in no index) | 88 | 100 |
| ImpactMesh score (standalone; in no index) | No data | No data |
| Remote sensing and raster analysis score | 77 | 89 |
| GIS analysis score | 75 | 94 |
| Climate and time series score | 63 | 75 |
| Spatial statistics score | 54 | 62 |
| Making maps score | 65 | 88 |
| Recognising infeasible requests score | 62 | 82 |
| Cost per task | $0.22 | $0.25 |
| Time per task (at 100 output tokens/s) | 4.7 min (estimated) | 1.4 min |
| Tokens per attempt | 840k | 174k |
| Turns per attempt | 17.6 | 6.9 |
| Input price per 1M tokens | $0.45 | $4.00 |
| Output price per 1M tokens | $3.20 | $20.00 |
| Context window | 262,144 | 1,000,000 |
| Image input | Yes | Yes |
| Developer | Alibaba (Qwen) | Anthropic |
Frequently asked questions
Which scores higher on the Geospatial Agent Index, Qwen 3.8 27B (Reasoning), Qwen Code or Claude Opus 5.5 (xhigh), Claude Code?
Claude Opus 5.5 (xhigh), Claude Code, 85 to 69.
Which is cheaper per task, Qwen 3.8 27B (Reasoning), Qwen Code or Claude Opus 5.5 (xhigh), Claude Code?
Qwen 3.8 27B (Reasoning), Qwen Code, $0.22 to $0.25.
Which writes fewer output tokens per task, Qwen 3.8 27B (Reasoning), Qwen Code or Claude Opus 5.5 (xhigh), Claude Code?
Claude Opus 5.5 (xhigh), Claude Code, 5k to 28k.
Which has the larger context window, Qwen 3.8 27B (Reasoning), Qwen Code or Claude Opus 5.5 (xhigh), Claude Code?
Claude Opus 5.5 (xhigh), Claude Code, 1,000,000 tokens to 262,144 tokens.