Claude Fable 5.1 (medium) vs Claude Opus 5 (high)
Results updated 16 November 2026 · Both in Claude Code · How we benchmark
Verdict

Claude Fable 5.1 (medium) edges Claude Opus 5 (high) by 1 point, and is faster; Claude Opus 5 (high) is cheaper.
- Cost per task
- $0.33 vs $0.32
- Time per task
- 0.8 min vs 1.1 min
- Tokens per attempt
- 107k vs 173k
- Image input
- No data vs Yes
Claude Fable 5.1 (medium), Claude Code scores higher on GeoBenchX and Vision agents; Claude Opus 5 (high), Claude Code scores higher on Earth-Bench V2 and GS-QA2. Claude Opus 5 (high), Claude Code is cheaper ($0.32 against $0.33 per task), but Claude Fable 5.1 (medium), Claude Code is faster (0.8 min against 1.1 min).
Where they differ most
By kind of work, share of tasks passed, 0 to 100 · Higher is better
| Kind of work | Claude Fable 5.1 (medium) | Claude Opus 5 (high) |
|---|---|---|
| Climate and time series | 74 | 80 |
| Change detection | 72 | 68 |
| Remote sensing and raster analysis | 87 | 85 |
| Making maps | 84 | 82 |
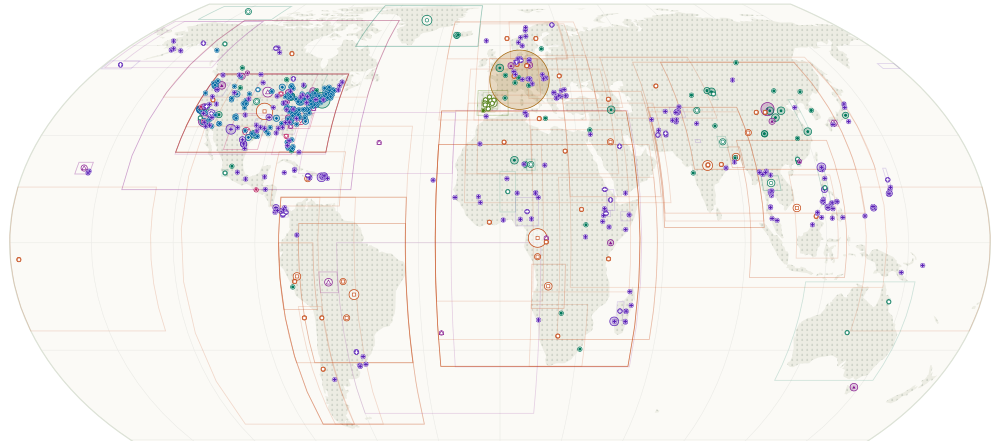 Where the tasks are set: each kind of work links to its tasks and scores
Charts for each: Claude Fable 5.1 (medium), Claude Code · Claude Opus 5 (high), Claude Code.
Side by side
| Metric | Claude Fable 5.1 (medium), Claude Code | Claude Opus 5 (high), Claude Code |
|---|---|---|
| Spatial Agent Index: Text only | 81 | 80 |
| Spatial Agent Index: Text + vision | 81 | 79 |
| Earth-Bench V2 score | 73 | 74 |
| GeoBenchX score | 81 | 75 |
| GS-QA2 score | 89 | 91 |
| Vision agents score | 81 | 77 |
| GeoAgentBench score (Guided workflows; not in the Agent Index) | 100 | 100 |
| GeoAnalystBench score (Guided workflows; not in the Agent Index) | 100 | 89 |
| OGD4All score (standalone; in no index) | 97 | 95 |
| GeoNatureAgent score (standalone; in no index) | 100 | 100 |
| MultiGlobeQA score (standalone; in no index) | 78 | 79 |
| GeoAgentEval score (standalone; in no index) | 96 | 96 |
| OpenEarthAgent Maps score (standalone; in no index) | No data | 99 |
| OpenEarthAgent Sentinel-2 score (standalone; in no index) | No data | 100 |
| GS-QA2 Full score (standalone; in no index) | No data | 86 |
| Place and coordinate tasks score (standalone; in no index) | No data | No data |
| InSAR Regional Snow Mapping score (standalone; in no index) | No data | 100 |
| Remote sensing and raster analysis score | 87 | 85 |
| Change detection score | 72 | 68 |
| GIS analysis score | 86 | 88 |
| Climate and time series score | 74 | 80 |
| Making maps score | 84 | 82 |
| Cost per task | $0.33 | $0.32 |
| Time per task (at 100 output tokens/s) | 0.8 min | 1.1 min |
| Tokens per attempt | 107k | 173k |
| Turns per attempt | 4.9 | 7.2 |
| Input price per 1M tokens | $10.00 | $5.00 |
| Output price per 1M tokens | $50.00 | $25.00 |
| Context window | 200,000 | 1,000,000 |
| Developer | Anthropic | Anthropic |
Frequently asked questions
Which scores higher on the Spatial Agent Index, Claude Fable 5.1 (medium), Claude Code or Claude Opus 5 (high), Claude Code?
Claude Fable 5.1 (medium), Claude Code, 81 to 80.
Which is cheaper per task, Claude Fable 5.1 (medium), Claude Code or Claude Opus 5 (high), Claude Code?
Claude Opus 5 (high), Claude Code, $0.32 to $0.33.
Which writes fewer output tokens per task, Claude Fable 5.1 (medium), Claude Code or Claude Opus 5 (high), Claude Code?
Claude Fable 5.1 (medium), Claude Code, 2k to 4k.
Which has the larger context window, Claude Fable 5.1 (medium), Claude Code or Claude Opus 5 (high), Claude Code?
Claude Opus 5 (high), Claude Code, 1,000,000 tokens to 200,000 tokens.